Monitoring Contracts That Encode Agent Intent Not Just Agent Execution
Contracts that test agent traces against intent catch failures that all-green logs miss.
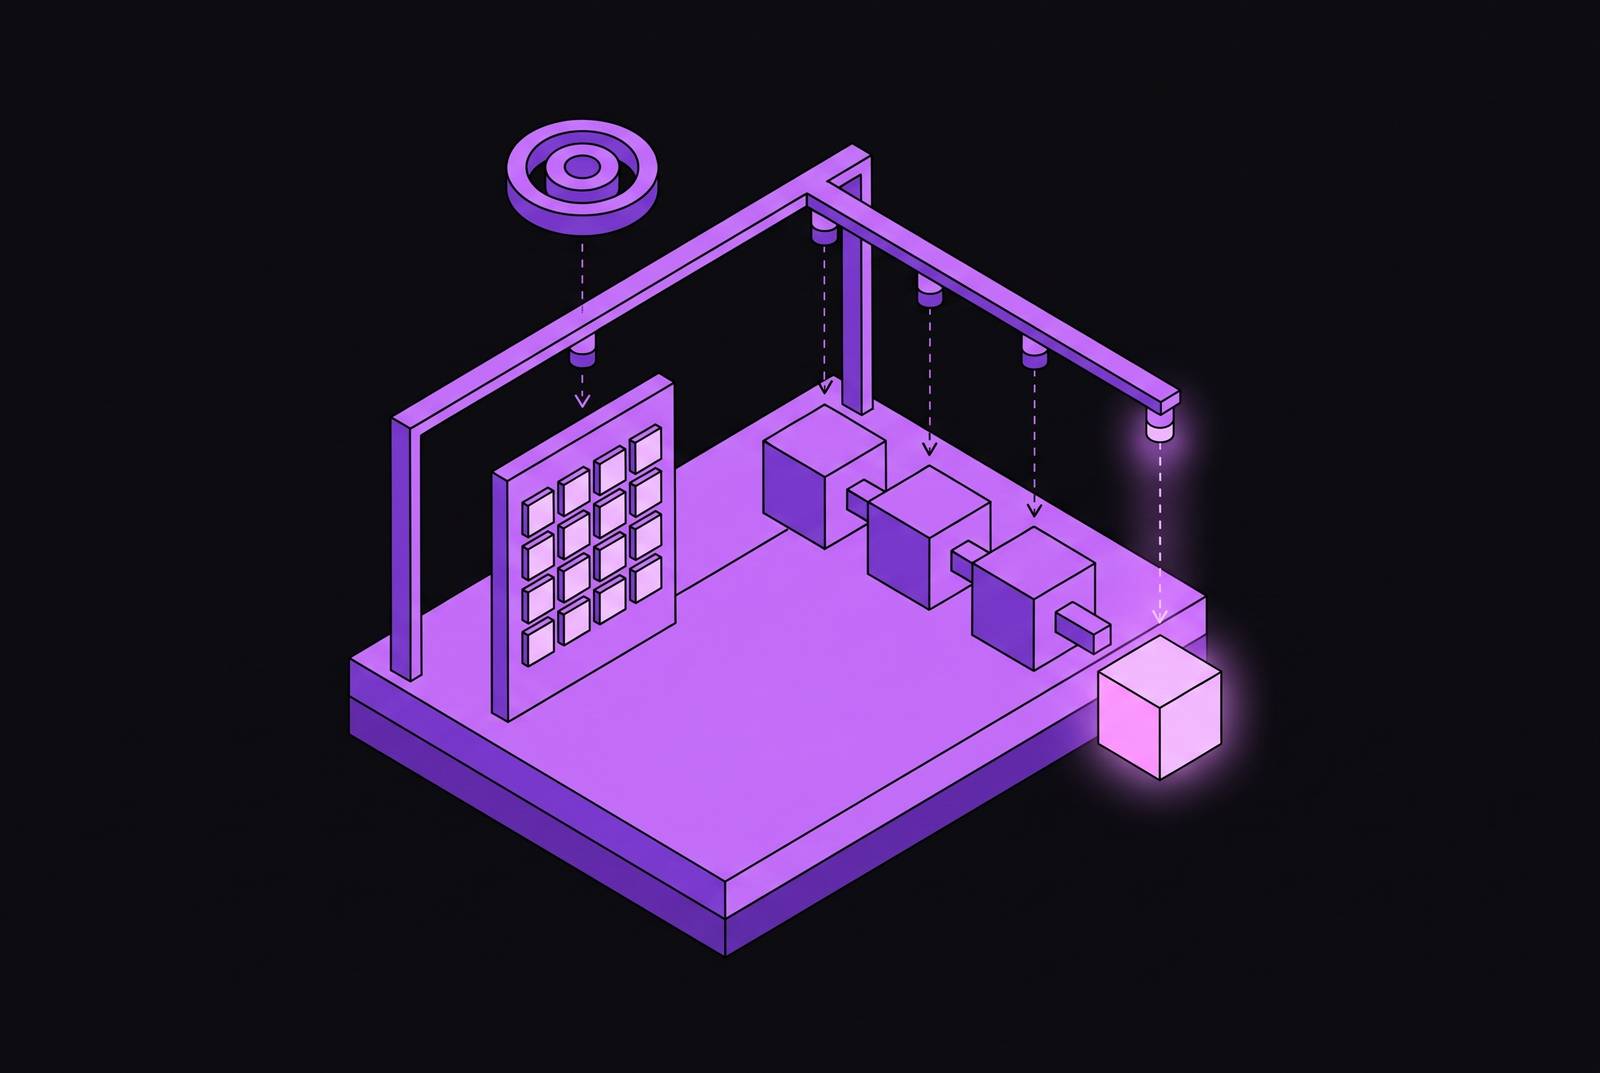
Silent failure detection for AI agents in production requires auditing what the agent did against what it was instructed to accomplish. Monitoring contracts that encode agent intent turn goals, permitted actions, and required behaviors into testable assertions over production traces. Execution monitoring establishes whether a run completed. Intent-contract monitoring establishes whether it completed the right task without violating policy.
Why execution-only monitoring cannot see the failures that matter
The assumption that healthy infrastructure means a healthy agent breaks as soon as an agent makes a wrong decision through a functioning tool. Traditional APM asks whether the service is up, while agent monitoring must also ask whether its decisions are correct. An agent can return HTTP 200, keep latency flat, and write all-green logs while giving a confident wrong answer.
Consider a support agent that refunds invoice #4417 instead of #4471 because it hallucinates a transposed ID inside a tool call. Every log line says the call succeeded, and the team learns about the mistake two days later through an angry email. A logistics routing agent can fail just as quietly when a downstream API renames incident_count to num_incidents without a corresponding tool-schema update. It then makes decisions with context missing while the system stays all-green. Both failures can happen without an exception or a latency spike.
These failures are not hidden because execution telemetry is inaccurate. The record correctly says that the calls completed. What it lacks is a standard for deciding whether the arguments, retrieved context, and resulting actions served the request. More detail on execution alone cannot give it that standard.
How agents fail — and why the failure is almost never where the symptom appears
An agent’s final output can expose a fault introduced several steps earlier, in a different part of the run. Tool-schema drift corrupts the context used by downstream decisions even when the call returns 200. Retrieval failures put the wrong document into an otherwise plausible answer. The symptom appears after the causal step has passed. A point-in-time execution check cannot reconstruct that relationship.
An agent may decompose a task incorrectly and pursue a subtask the user never requested. Memory drift can then hide the original goal over a longer chain, even when each output looks reasonable on its own. No single step is necessarily obviously wrong. The failure becomes visible through the relationship between the opening request and the full sequence.
Memory poisoning extends that problem across sessions. A successful injection can cause an agent to propagate a bad instruction without logging an execution error. Microsoft’s AI Red Team highlighted memory poisoning in its June 2026 v2.0 taxonomy, but the category was already present in v1.0 in April 2025. The update added seven categories, among them Agentic Supply Chain Compromise, Goal Hijacking, and Session Context Contamination. Across these failures, the execution record establishes completion alone.
What a monitoring contract that encodes intent actually is
An intent-first monitoring contract makes the agent’s instructions the specification against which its traces are evaluated. It encodes the initiating user intent, permitted tool sequences, conditions for calling each tool, and applicable policies. Those policies include refund eligibility, data-access boundaries, and escalation thresholds. It also defines a correct session outcome. Success means accomplishing the requested task within those constraints, rather than receiving a successful final response code.
This changes the role of the instructions. They are no longer only a prompt that guides generation, but also a standard that can expose a violation. Most agent architectures lack a mandatory evaluation point between deciding on an action and taking it. A contract makes that decision testable, whether the check is applied before an action or through trace auditing afterward. Post-action auditing detects a violation. It does not undo the action.
The session is the appropriate unit for that broader judgment because it groups the traces of a multi-turn interaction. At this scope, it is possible to see when questions repeat, intent changes, and goals go unfinished. Local success is not enough to establish completion. A schema check can establish that a refund request is well-formed, while a semantic assertion tests whether it targets the requested invoice and respects the refund policy.
The trace structure that makes intent auditable
Intent auditing needs a record with at least four span types. Tool-call spans record the tool name, arguments, raw output, duration, retry count, and error state. Argument-level recording exposes hallucinated IDs and wrong-entity lookups. Reasoning spans record the model’s plan, selected action, observation, and next-step decision, making plan drift and wrong-branch selection inspectable. A single undifferentiated LLM span cannot provide that separation.
State transition spans record working memory before and after each step, context edits, and handoff payloads. They expose context loss and summarization drift. Memory operation spans record long-term-store reads and writes, including queries, returned entries, relevance scores, and freshness. These records make stale reads, wrong-entity retrieval, and memory leakage between users inspectable. A top-level invoke_agent span ties the original user intent to child spans for LLM calls, tool executions, and memory operations.
Evaluation then operates at three distinct granularities. Final-response, or black-box, evaluation asks whether the answer matched the intent, but cannot locate the fault. Trajectory, or glass-box, evaluation examines whether the full tool sequence served that intent correctly and efficiently. Single-step, or white-box, evaluation tests each action against its local contract. Together, these views connect an incorrect outcome to the step that caused it.
OpenTelemetry GenAI semantic conventions provide a common vocabulary for this instrumentation. As of specification v1.41, all gen_ai.* attributes have Development stability, while the inherited core attributes error.type, server.address, and server.port are Stable. The names of attributes can thus change without a major version bump. Teams should instrument against the specification for portability while tracking its stability status. The baseline histograms remain gen_ai.client.operation.duration and gen_ai.client.token.usage, with token consumption broken down by input and output.
Turning production traces into an automated intent-auditing layer
An evaluator scores sampled live traces against the contract, rather than waiting for a complaint to reveal a wrong answer. Offline datasets serve a different purpose. They establish performance on recorded cases, but cannot establish whether production quality degraded yesterday. Live evaluation gives teams that missing signal without a person having to review every trace.
For that signal to remain useful, the alerting policy must distinguish recurring failures from isolated score drops. The recommended approach samples production traces and uses an evaluator from a different model family than the generating model to reduce score contamination. A practical alerting heuristic is three consecutive failures in the same category. Failures that keep happening should be grouped into issues, without a separate alert for every trace. The pattern is the unit engineers can investigate.
For MCP-connected, tool-using agents, five criteria make the contract measurable. Tool selection accuracy tests whether dynamically discovered tools were selected in the right order, while argument correctness tests semantic appropriateness as well as schema compliance. Task completion rate assesses the end-to-end goal. Chain efficiency checks for loops and repeated calls that were not needed, while context utilization checks whether the agent used the context it had correctly.
The recommended feedback loop automatically turns each detected production failure into an evaluation case. That case becomes a regression check after the fix, preserving the behavior production demonstrated instead of relying on hand-written assertions afterward. Prompt changes also need an auditable quality history. When a system prompt changes, the evaluation dataset diff belongs in the same pull request. This loop becomes operational only when its findings reach the engineers and systems responsible for repairs.
Getting intent-contract violations to engineers — and to their coding agents
A useful alert provides diagnostic context by identifying the violated contract clause, grouping the failure by issue type, and including the full trace. Routing grouped issues to Slack puts that context into the triage workflow without requiring a separate dashboard merely to understand the failure. Engineers need both the wrong outcome and the evidence connecting it to a cause.
MCP provides a route from that diagnosis into a coding-agent workflow. The monitoring layer can hand over the trace, violated clause, and grouped issue so that a coding agent can propose a prompt fix or tool-schema correction. The proposal is not the final judgment. Evaluation must check for regressions before release, and production traces with the same kind of failure must be scored again afterward. If the issue recurs, the alert fires again, while the evaluation case remains in the regression suite.
Where intent-contract monitoring is highest-stakes: customer support, finance, and CRM
In customer support, the cost of finding failures late is visible in rising churn. Customers who run into loops, lose context across handoffs, or get confident wrong answers do not always escalate right away. The service can look healthy throughout that deterioration. ServiceNow reported in April 2026 that AI agents were handling a substantial share of its own customer support case workflows. At that scale, contracts that cover refund policy, escalation rules, and data-access permissions give teams a way to find violations in traces before churn signals a failure.
Finance adds regulatory exposure to the operational cost. Every query, record read, and workflow step an agent takes in a regulated domain should appear in an immutable, timestamped log. The EU AI Act’s high-risk system obligations, phasing in through August 2026 and August 2027, include risk management, data governance, logging, transparency, and human oversight. Execution history alone is not the complete account. An intent contract also records what the agent was permitted to do and whether its behavior stayed within that boundary.
CRM workflows add the problem of persistent state mutation. An agent can complete individual tool calls correctly while pursuing the wrong session-level goal, leaving a record that documents successful writes without justifying them. Once the agent changes states, assigns owners, triggers payments, or contacts customers, a tamper-resistant history becomes necessary. Every write needs an auditable intent justification. The distinction from a chatbot is not conversational fluency, but the authority to change records and act on them.
Instrumenting the contract across the agent frameworks teams actually use
The contract is framework-agnostic, but its instrumentation is framework-specific. OpenAI Agents SDK provides built-in guardrails for parallel input validation that halts execution on failure, with tracing through OpenAI’s observability platform. Guardrails are the closest native analogue to a pre-action contract check. Semantic failures that get past them still need to be checked through trace-level evaluation. As of April 2026, the SDK also supports sandboxed code execution through providers including Blaxel, Cloudflare, Daytona, E2B, Modal, Runloop, and Vercel.
Mastra records spans for agent runs, workflow steps, tool calls, and model calls. It supports DuckDB storage for development and ClickHouse, PostgreSQL, MSSQL, MongoDB, or OracleDB for production. Its instrumentation surface makes tool-call, reasoning, state transition, and memory operation records reachable. Coverage is the starting point, and the contract supplies the criteria for evaluating whether those recorded steps served the requested goal.
Vercel AI SDK builds tracing on OpenTelemetry with minimal instrumentation effort. Its traces can be sent to the OpenTelemetry-compatible MLflow tracking server with minimal configuration. That common vocabulary supports evaluators that read traces across frameworks. Native framework adapters normalize spans, attributes, and events into the GenAI schema, while the OpenTelemetry SDK provides a fallback path for unsupported frameworks. The monitoring layer therefore fits over the existing stack.
Above those adapters, the steps the system must take stay the same. The platform records execution, audits it against the agent’s instructions, groups recurring failures, and delivers diagnostic context to engineers through Slack and to coding agents through MCP. Production failures become evaluation cases automatically. Proposed changes are tested against those cases, and subsequent production traces establish whether the failure recurs. The contract remains the standard from the first detected violation through the verified fix.